Import / Export a crawler's results
If you already run a dedicated crawler, a desktop one or an open-source one you host yourself, you can bring its findings into WordPress. SEO → Audit → Import / Export a crawler's results takes its export, matches each address to a page, and lists the problems in the Audit, each with a link to the page's editor.
This is a convenience rather than a necessity: the Audit, the rendered-page checks and the broken link checker cover the same ground from inside WordPress.
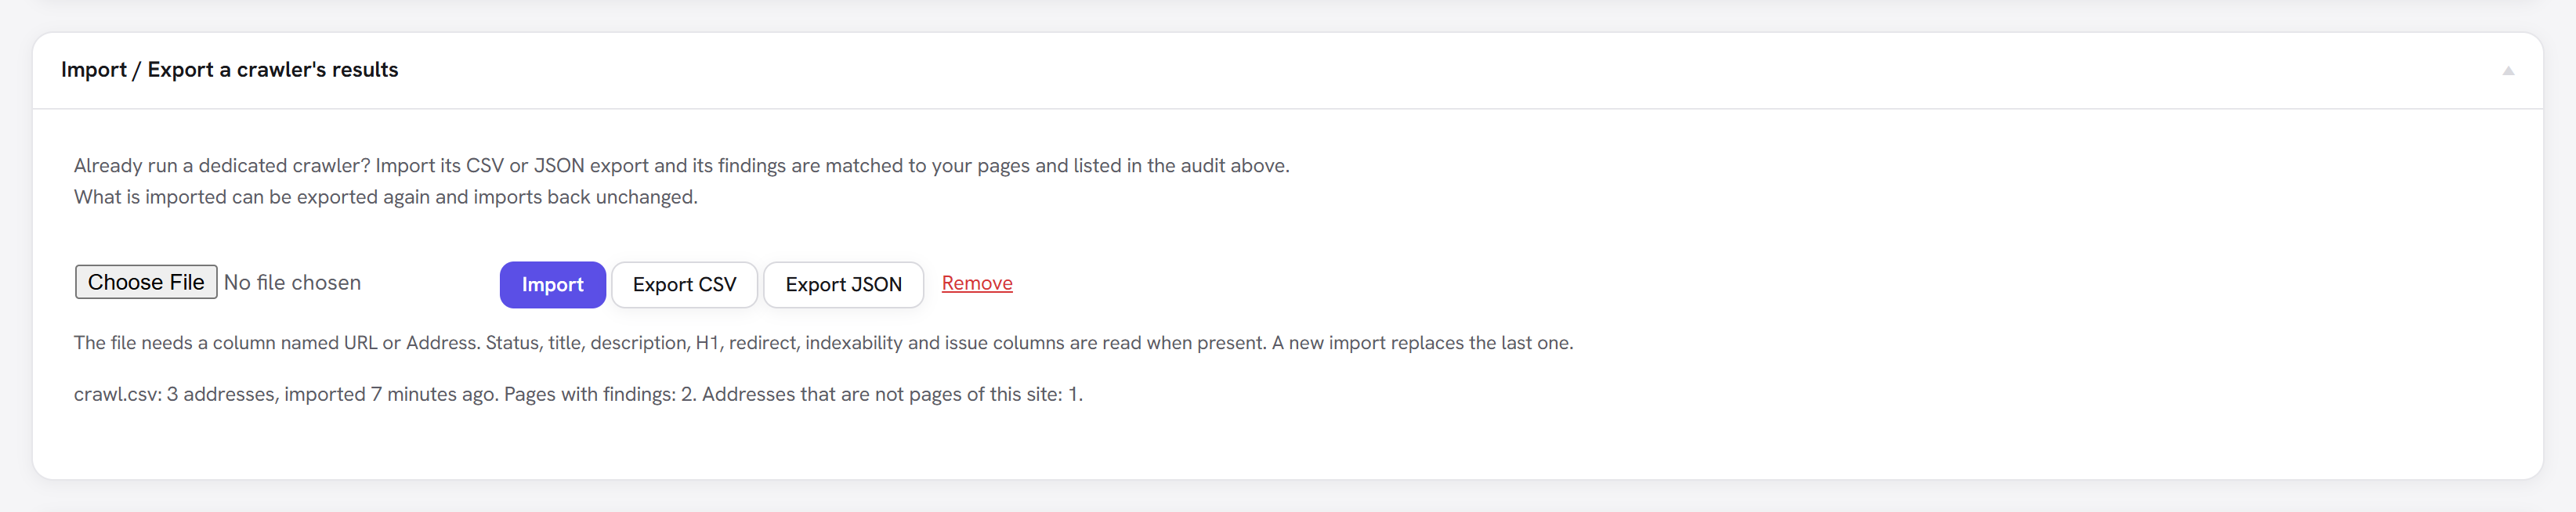
Importing
Choose a .csv, .tsv or .json file and press Import. A new import replaces the last one.
CSV and TSV files can be comma, semicolon or tab separated. JSON files can be a plain list of rows, or an
object with the list under rows, results, pages, urls or data.
Columns are found by name, ignoring capitals and punctuation, so Status Code and status_code are the same:
| Read as | Column names accepted |
|---|---|
| Address (required) | URL, Address, Page, Page URL, Loc, Link |
| Status | Status, Status Code, HTTP Status, Response Code, Code |
| Title | Title, Title 1, Page Title, Meta Title |
| Description | Description, Meta Description, Meta Description 1, Meta Desc |
| H1 | H1, H1-1, First H1, Heading 1 |
| Redirect | Redirect, Redirect URL, Redirect URI, Redirects To, Final URL, Location |
| Indexable | Indexable, Indexability, Is Indexable |
| Notes | Notes, Issue, Issues, Problems, Warnings, Errors |
Any other column is ignored, and a row without a full http:// or https:// address is skipped. Up to
20,000 rows are read.
What appears in the Audit
| Finding | When |
|---|---|
| The address answered an error | The status is 400 or above. |
| The address redirects | The status is 300 to 399. The destination is shown when the file has it. |
| No title, description or H1 | The status is 200 and the cell is empty. |
| The page cannot be indexed | Indexable is no, false, 0 or Non-Indexable. |
| Other findings | The notes column has text. It is shown as written. |
A column a crawler does not have is not read as a problem: only an empty cell in a column the file uses elsewhere counts. So a crawler that exports no descriptions does not report every page as missing one.
Addresses that are not pages of this site, such as archives and files, are kept and counted in the summary but do not appear in the Audit. Neither do pages that are no longer published.
Exporting
Export CSV and Export JSON download every imported row, in the shape shown above, including addresses that matched no page. Either file imports back unchanged, here or on another site. Remove deletes the import.
Limits
- It is a snapshot. Findings stay until you import again or remove them, however much the pages change.
- Columns outside the table above are not kept, so an export here holds less than the crawler's own file.
- Matching uses WordPress's own address lookup, so an address from another domain, such as a staging copy, will not match.