Index coverage
A page Google never kept cannot bring anyone to the site. Nothing else in WordPress tells the difference between nobody searches for this and it was never in the index — and those lead to completely different afternoons.
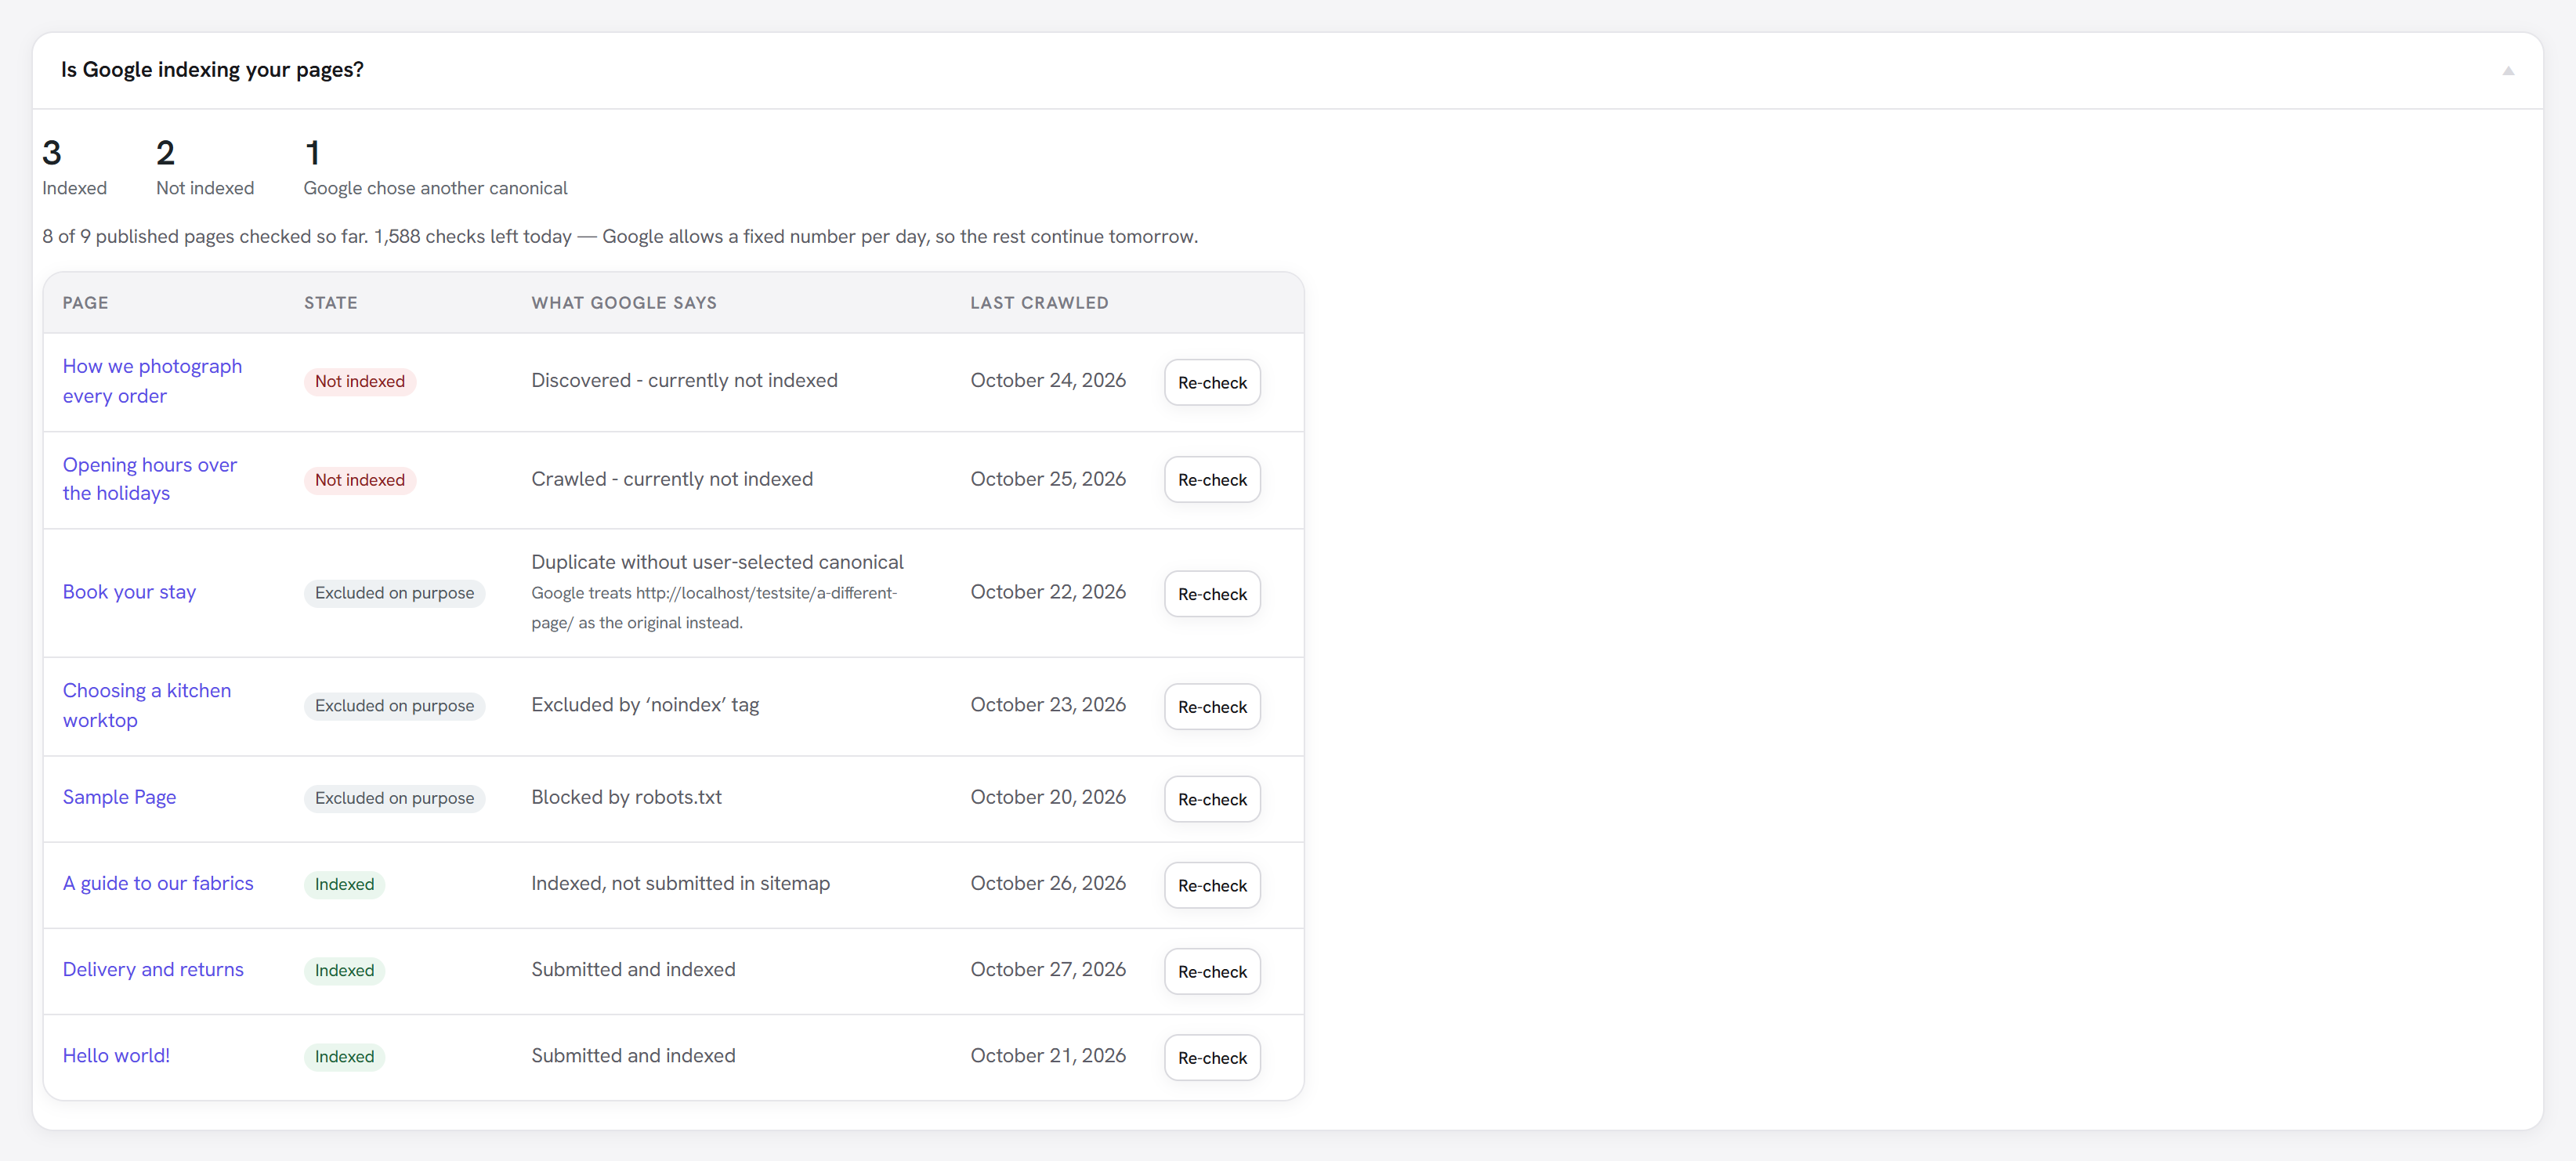
It runs on the Search Console connection you already set up. Same OAuth client, same read-only permission — there is no second credential and nothing further to connect.
What the states mean
| State | What happened | What to do |
|---|---|---|
| Indexed | Google kept the page. | Nothing. |
| Not indexed | Google saw it and did not keep it — "crawled, currently not indexed" or "discovered, currently not indexed". | The one worth your attention. Usually the page is thin, near-duplicate, or has nothing linking to it. |
| Excluded on purpose | A noindex, a robots.txt block, or a canonical pointing elsewhere. | Check it was deliberate. Often it was. |
| Not known yet | Google has not answered for this page. | Wait for the background check to reach it. |
The row also carries what Google itself says — "Duplicate without user-selected canonical", "Blocked by robots.txt" — because the specific phrase is the actionable part. A count of problems tells you nothing; a named cause tells you where to go.
When Google chose a different canonical
The most useful single line on the screen. If Google decided another URL is the original, this page is not competing on its own — whatever it earns is credited elsewhere. The report names the URL it chose, so you can decide whether that was right.
Why it takes a while
Google allows a fixed number of these checks per property per day. A site with several hundred pages cannot be swept on a page load, so:
- a background job works through a few pages an hour, oldest first, and pages never checked go to the front of the queue;
- the screen shows what has been gathered so far, with a count of how many pages remain;
- the extension spends against a daily budget it can see, held deliberately below Google's own limit so a sweep cannot eat the quota that on-demand checks need;
- a result is re-checked after about a month, because index state changes slowly.
:::note Why not a "check everything now" button There is no honest version of that button. It would either exhaust a day's quota on one click, or queue work and pretend it had finished. Re-check on a single row is immediate, because one check is a thing the budget can always afford. :::
The background job schedules itself once Search Console is connected, and removes itself if the connection is taken away.
What it cannot tell you
- Nothing about a page Google has never seen. If a URL was never discovered, there is no inspection result — which is itself worth knowing, and shows as Not known yet until a check runs.
- Nothing about a competitor's page. The API only answers for properties your connected Google account can see.
- Not a live reading. The answer reflects Google's last crawl, which is shown on each row, not the page as it stands this second.